







14d 23h
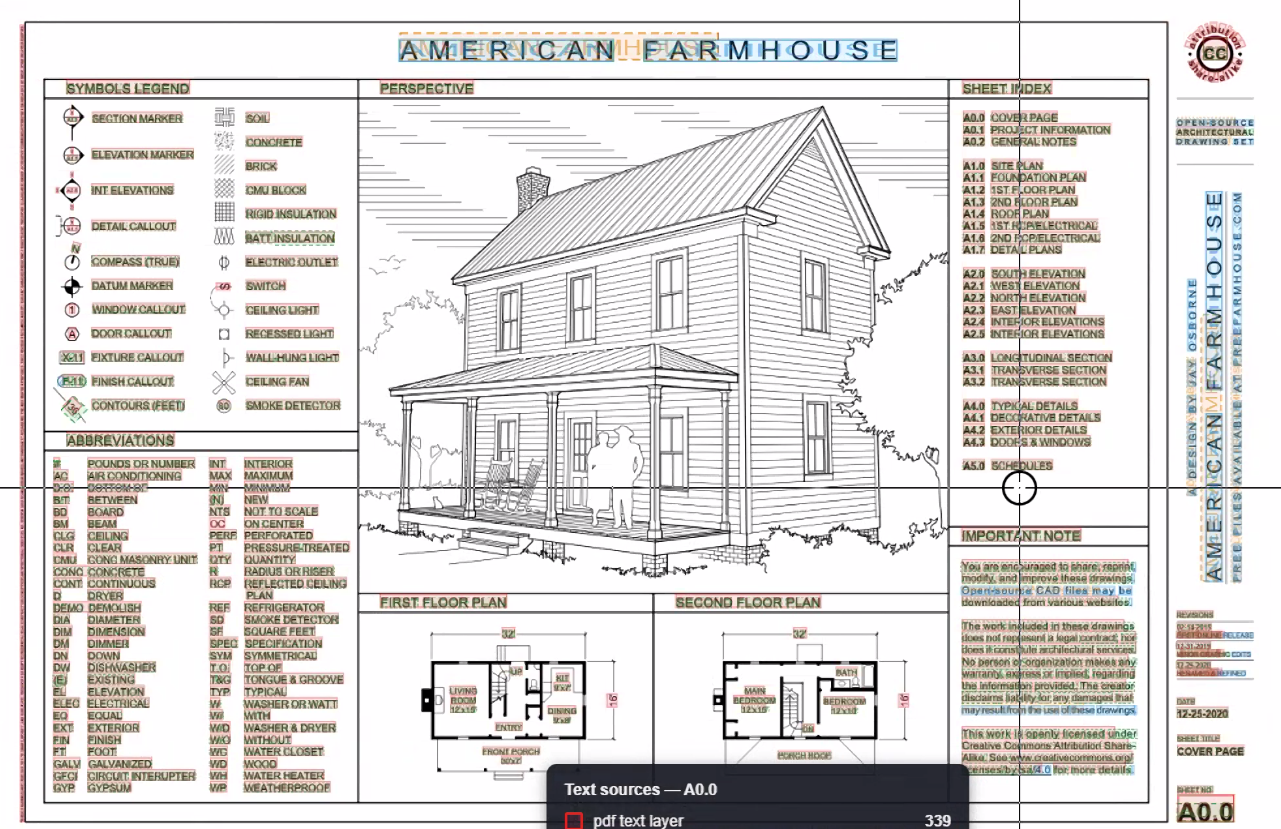
PDF Text / Merged with OCR Text
This is just a diagnostic view of the PDF Text merging with the OCR Text. We're working on making it more robust, primarily for improving search and MCP usability.

Jes 14d 22h
😁

Heber Allred zzTakeoff14d 22h
@Shawn Yep. The Dev Tools will be able to access this data. There is already a command Pages.extractText which has some of this already, but will be greatly improved.
@Jes All your dreams are coming true now 😁
👍1 You must be logged in to post replies. If you don't have an account you can signup here.